Main ideas
Learn one-sample test of means
Learn one-sample test of proportions
Learn two-sample test of means
Introduction to Global Health Data Science
Duke University
STA/GLHLTH 198 Fall 2026
2026-09-30
Learn one-sample test of means
Learn one-sample test of proportions
Learn two-sample test of means
Steps in hypothesis testing:
Start with two claims about the population (often about the value of a population parameter or about some potential association between two variables in the population). Call them claim 1 and claim 2.
Choose a sampling strategy, draft an analysis plan, collect data, and summarize data
Figure out how likely it is to see data like what we got, if claim 1 is true.
If our data would have been unlikely if claim 1 were true, then we reject claim 1 and deem claim 2 worthy of further study. Otherwise, we cannot reject claim 1.
Hypothesize a value, \(\mu_0\), and set up \(H_0\) and \(H_A\)
Take a random sample of size \(n\) and calculate summary statistics (e.g., sample mean and variance)
Is it likely that the sample, or one even more extreme, came from a population with mean \(\mu_0\)?
Draw conclusions
We set up the hypotheses to cover all the possibilities for \(\mu\) and consider three possibilities.
| \(H_0\) | \(H_A\) | |
|---|---|---|
| Two-sided | \(\mu=\mu_0\) | \(\mu \neq \mu_0\) |
| One-sided | \(\mu>\mu_0\) | \(\mu \leq \mu_0\) |
| One-sided | \(\mu<\mu_0\) | \(\mu \geq \mu_0\) |
One-sided tests are pretty rare.
We set up the hypotheses to cover all the possibilities for \(\pi\) and consider three possibilities.
| \(H_0\) | \(H_A\) | |
|---|---|---|
| Two-sided | \(\pi=\pi_0\) | \(\pi \neq \pi_0\) |
| One-sided | \(\pi>\pi_0\) | \(\pi \leq \pi_0\) |
| One-sided | \(\pi<\pi_0\) | \(\pi \geq \pi_0\) |
One-sided tests are pretty rare.
To conduct the hypothesis test, we use what we learned about the sampling distribution of the sample mean \(\bar{X}\). If the underlying population is normally distributed (or \(n\) is pretty large), then the random variable \[t=\frac{\bar{X}-\mu_0}{\frac{s}{\sqrt{n}}}\] has a \(t_{n-1}\) distribution, and we can use a t-test of our hypothesis by using software (R t.test). This test is called the one sample t-test.
For a test of a proportion, where we don’t have to estimate a separate variance parameter, we could use a z-statistic and compare to a \(N(0,1)\) distribution or even better the exact binomial distribution itself (R binom.test).
You will almost always use software to calculate the test statistic and p-value, but it is important to understand the big concepts behind the scenes.
First, think about our test statistic \[t=\frac{\bar{X}-\mu_0}{\frac{s}{\sqrt{n}}}.\]
\(\bar{X}-\mu_0\) makes sense, because we want to look at how far our sample mean is from the hypothesized population mean
Whether \(\bar{X}-\mu_0\) is big depends on the standard deviation. For example, a difference of \(\bar{X}-\mu_0=1\) is a small difference if we are looking at weight in g but huge for height in m. This is why we standardize the difference by dividing by the estimated SD of the mean, so \(t\) is a measure of how many SDs apart \(\mu_0\) and \(\bar{X}\) are from each other
Think about our test statistic \[t=\frac{\bar{X}-\mu_0}{\frac{s}{\sqrt{n}}}.\]
| \(H_0\) | \(H_A\) | |
|---|---|---|
| Two-sided | \(\mu=\mu_0\) | \(\mu \neq \mu_0\) |
| One-sided | \(\mu>\mu_0\) | \(\mu \leq \mu_0\) |
| One-sided | \(\mu<\mu_0\) | \(\mu \geq \mu_0\) |
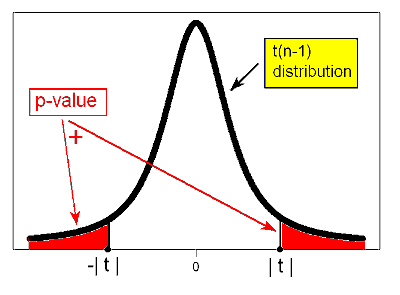
For a two-sided test, the p-value is the probability of seeing a t statistic with absolute value as big as, or larger than, what we saw in our data. Recall \[t=\frac{\bar{X}-\mu_0}{\frac{s}{\sqrt{n}}}.\]
| \(H_0\) | \(H_A\) | |
|---|---|---|
| Two-sided | \(\mu=\mu_0\) | \(\mu \neq \mu_0\) |
| One-sided | \(\mu>\mu_0\) | \(\mu \leq \mu_0\) |
| One-sided | \(\mu<\mu_0\) | \(\mu \geq \mu_0\) |
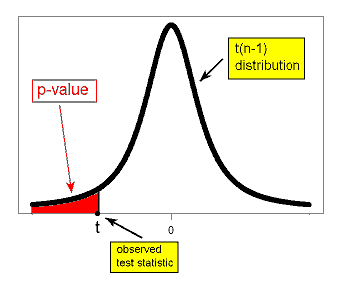
For a one-sided test with \(H_0: \mu > \mu_0\), the p-value is the probability of seeing a t statistic with value the same size, or smaller than, what we saw in our data. Recall \[t=\frac{\bar{X}-\mu_0}{\frac{s}{\sqrt{n}}}.\]
| \(H_0\) | \(H_A\) | |
|---|---|---|
| Two-sided | \(\mu=\mu_0\) | \(\mu \neq \mu_0\) |
| One-sided | \(\mu>\mu_0\) | \(\mu \leq \mu_0\) |
| One-sided | \(\mu<\mu_0\) | \(\mu \geq \mu_0\) |
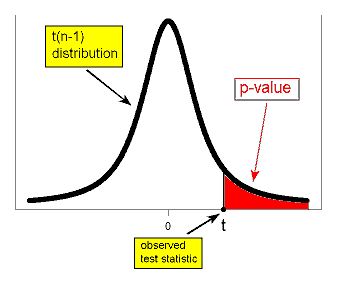
For a one-sided test with \(H_0: \mu < \mu_0\), the p-value is the probability of seeing a t statistic with value the same size, or larger than, what we saw in our data. Recall \[t=\frac{\bar{X}-\mu_0}{\frac{s}{\sqrt{n}}}.\]
The choice between a one-sided and a two-sided test can be highly controversial because a one-sided test will have a p-value that is half that of the corresponding two-sided test, due to the symmetry of the \(t\) distribution. Sometimes a scientist will (unethically) choose a one-sided test on nonscientific grounds. To protect against this, some journal editors are extremely reluctant to publish studies using one-sided tests.
Usually, you have a pretty good idea what will happen (you do have to get research funding using some justification!). In this case, why not always do one-sided tests?
New generation of antiarrhythmic agents strongly believed to have fewer side effects with much greater efficacy
Due to strength of this belief, one-sided test was selected
Recruitment was difficult because many physicians refused to randomize their patients when chance of NOT getting the new drugs was 50%
The trial showed new generation drugs associated with 4x the mortality as status quo
P-value was 0.0003 in the wrong direction (i.e., new drug worse), but with a one-sided test that direction is part of the null hypothesis of status quo, so you don’t reject the null
Fortunately the Data Safety and Monitoring Board stopped the trial quickly
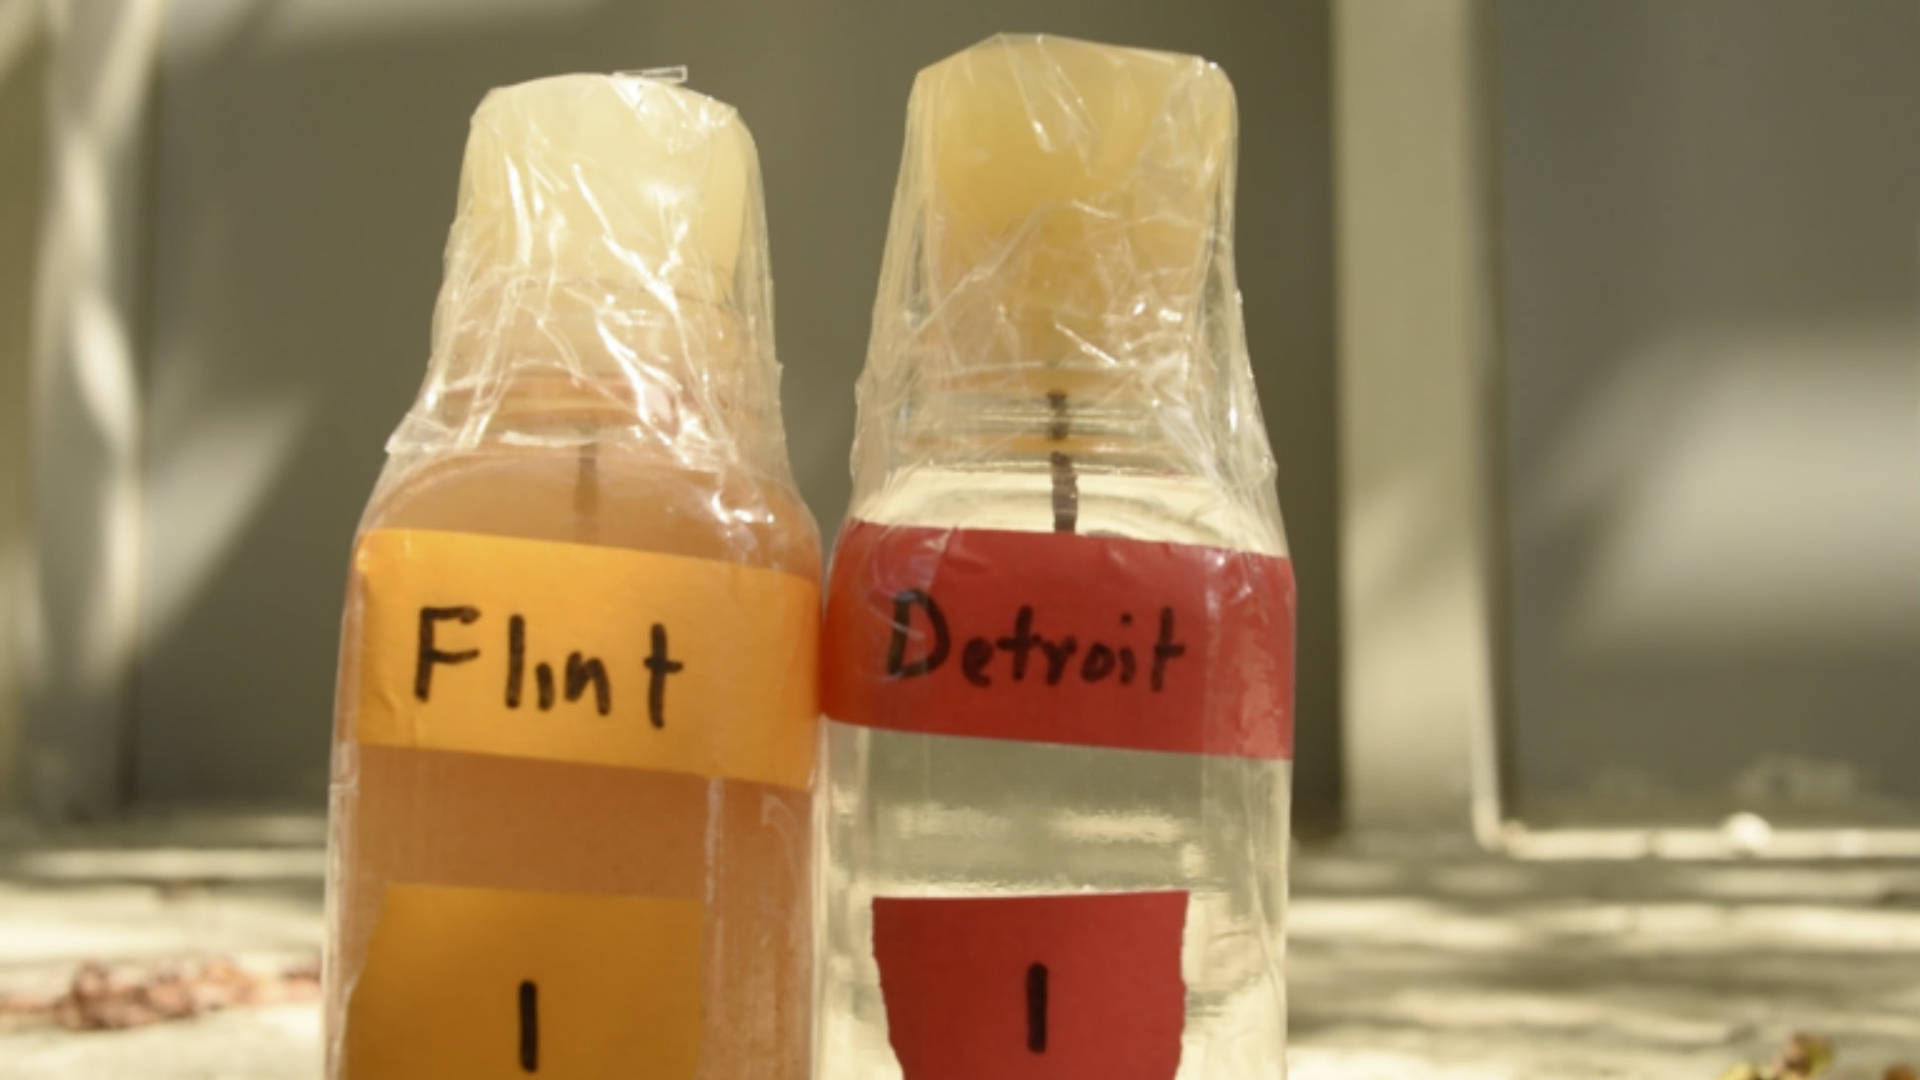
From April 25, 2014 to October 15, 2015, the water supply source for Flint, MI was switched to the Flint River from the Detroit water system. Without corrosion inhibitors, the Flint River water, which is high in chloride, caused lead from aging pipes to leach into the water supply. We have data from Flint collected as part of a citizen-science project involving Virginia Tech researchers.
Let’s conduct an \(\alpha=0.05\) t-test of \(H_0: \mu=15\) versus \(H_A: \mu \neq 15\).
flint=read_excel("../data/Flint-Samples.xlsx",sheet=1)
flint=rename(flint, "Pb_initial"="Pb Bottle 1 (ppb) - First Draw")
t.test(flint$Pb_initial, mu=15)#>
#> One Sample t-test
#>
#> data: flint$Pb_initial
#> t = -3.3244, df = 270, p-value = 0.001009
#> alternative hypothesis: true mean is not equal to 15
#> 95 percent confidence interval:
#> 8.067422 13.224563
#> sample estimates:
#> mean of x
#> 10.64599
The null value 15 is not in our CI, and the p-value is quite small. We have evidence to reject the null hypothesis, and fortunately the mean lead level appears to be less than 15.
We can use a bootstrap procedure in hypothesis testing, similar to the one we used to calculate a confidence interval.
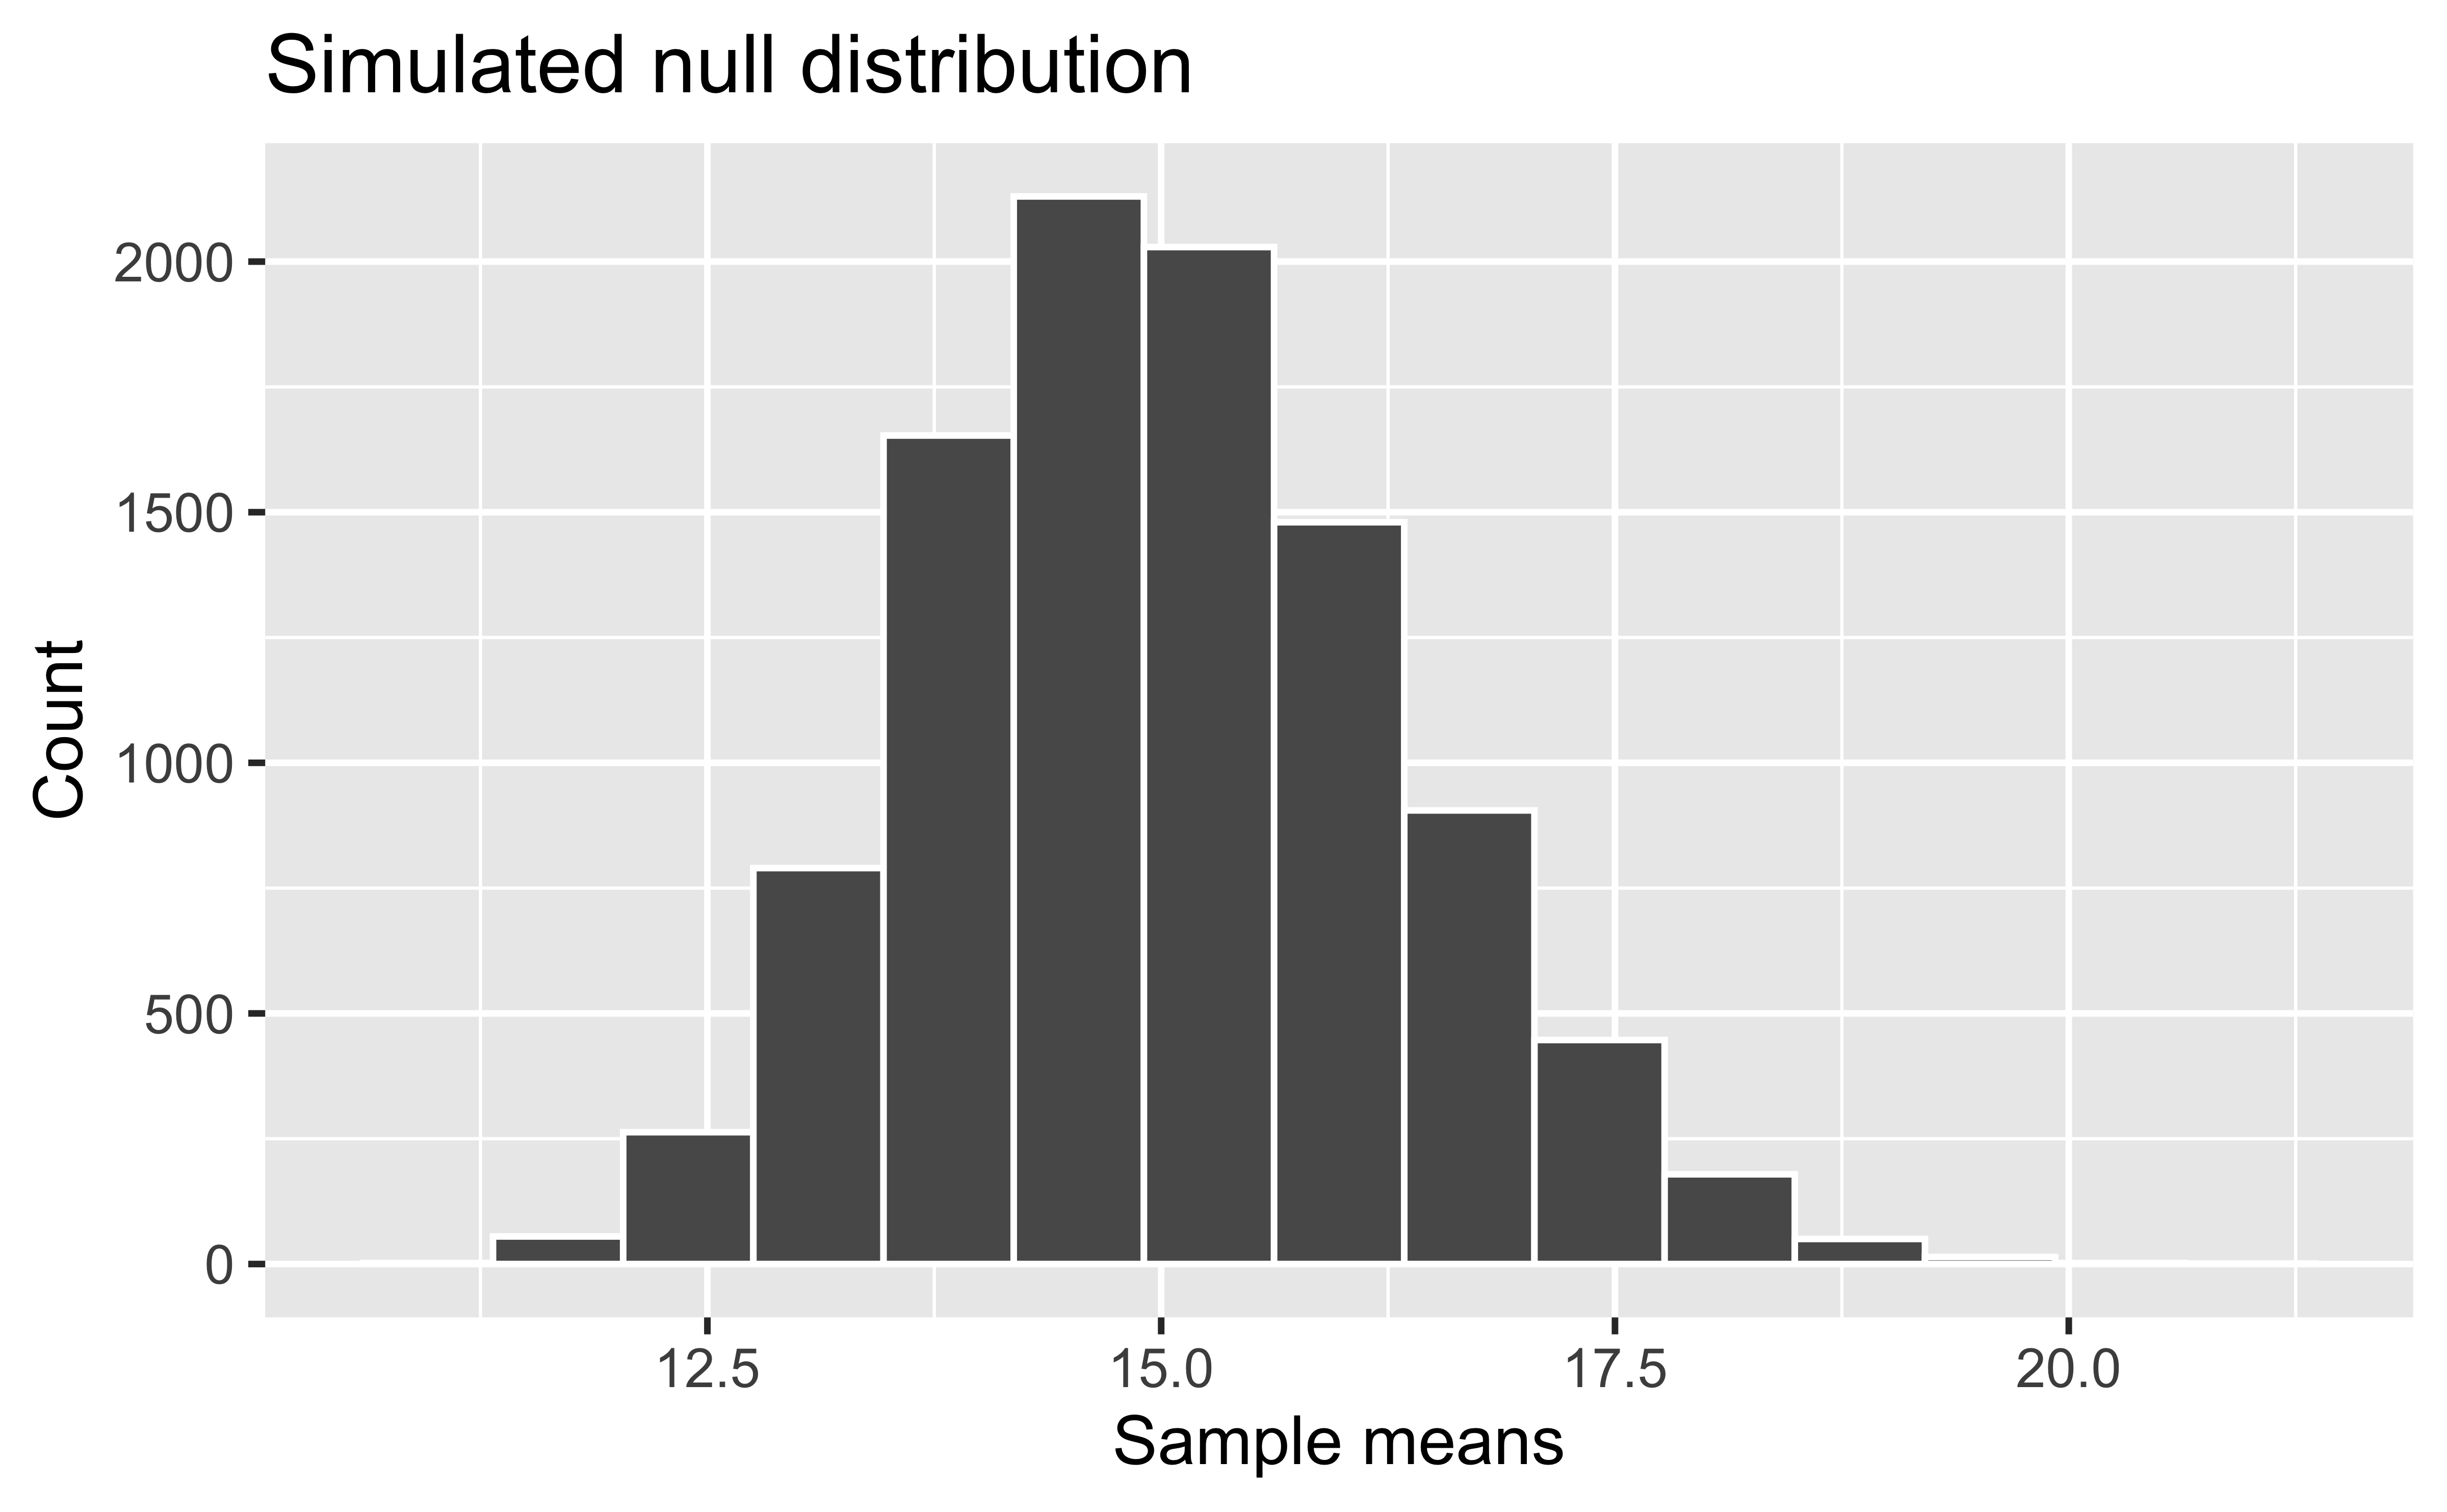
First, let’s simulate the null distribution – what we expect to see if the mean is 15.
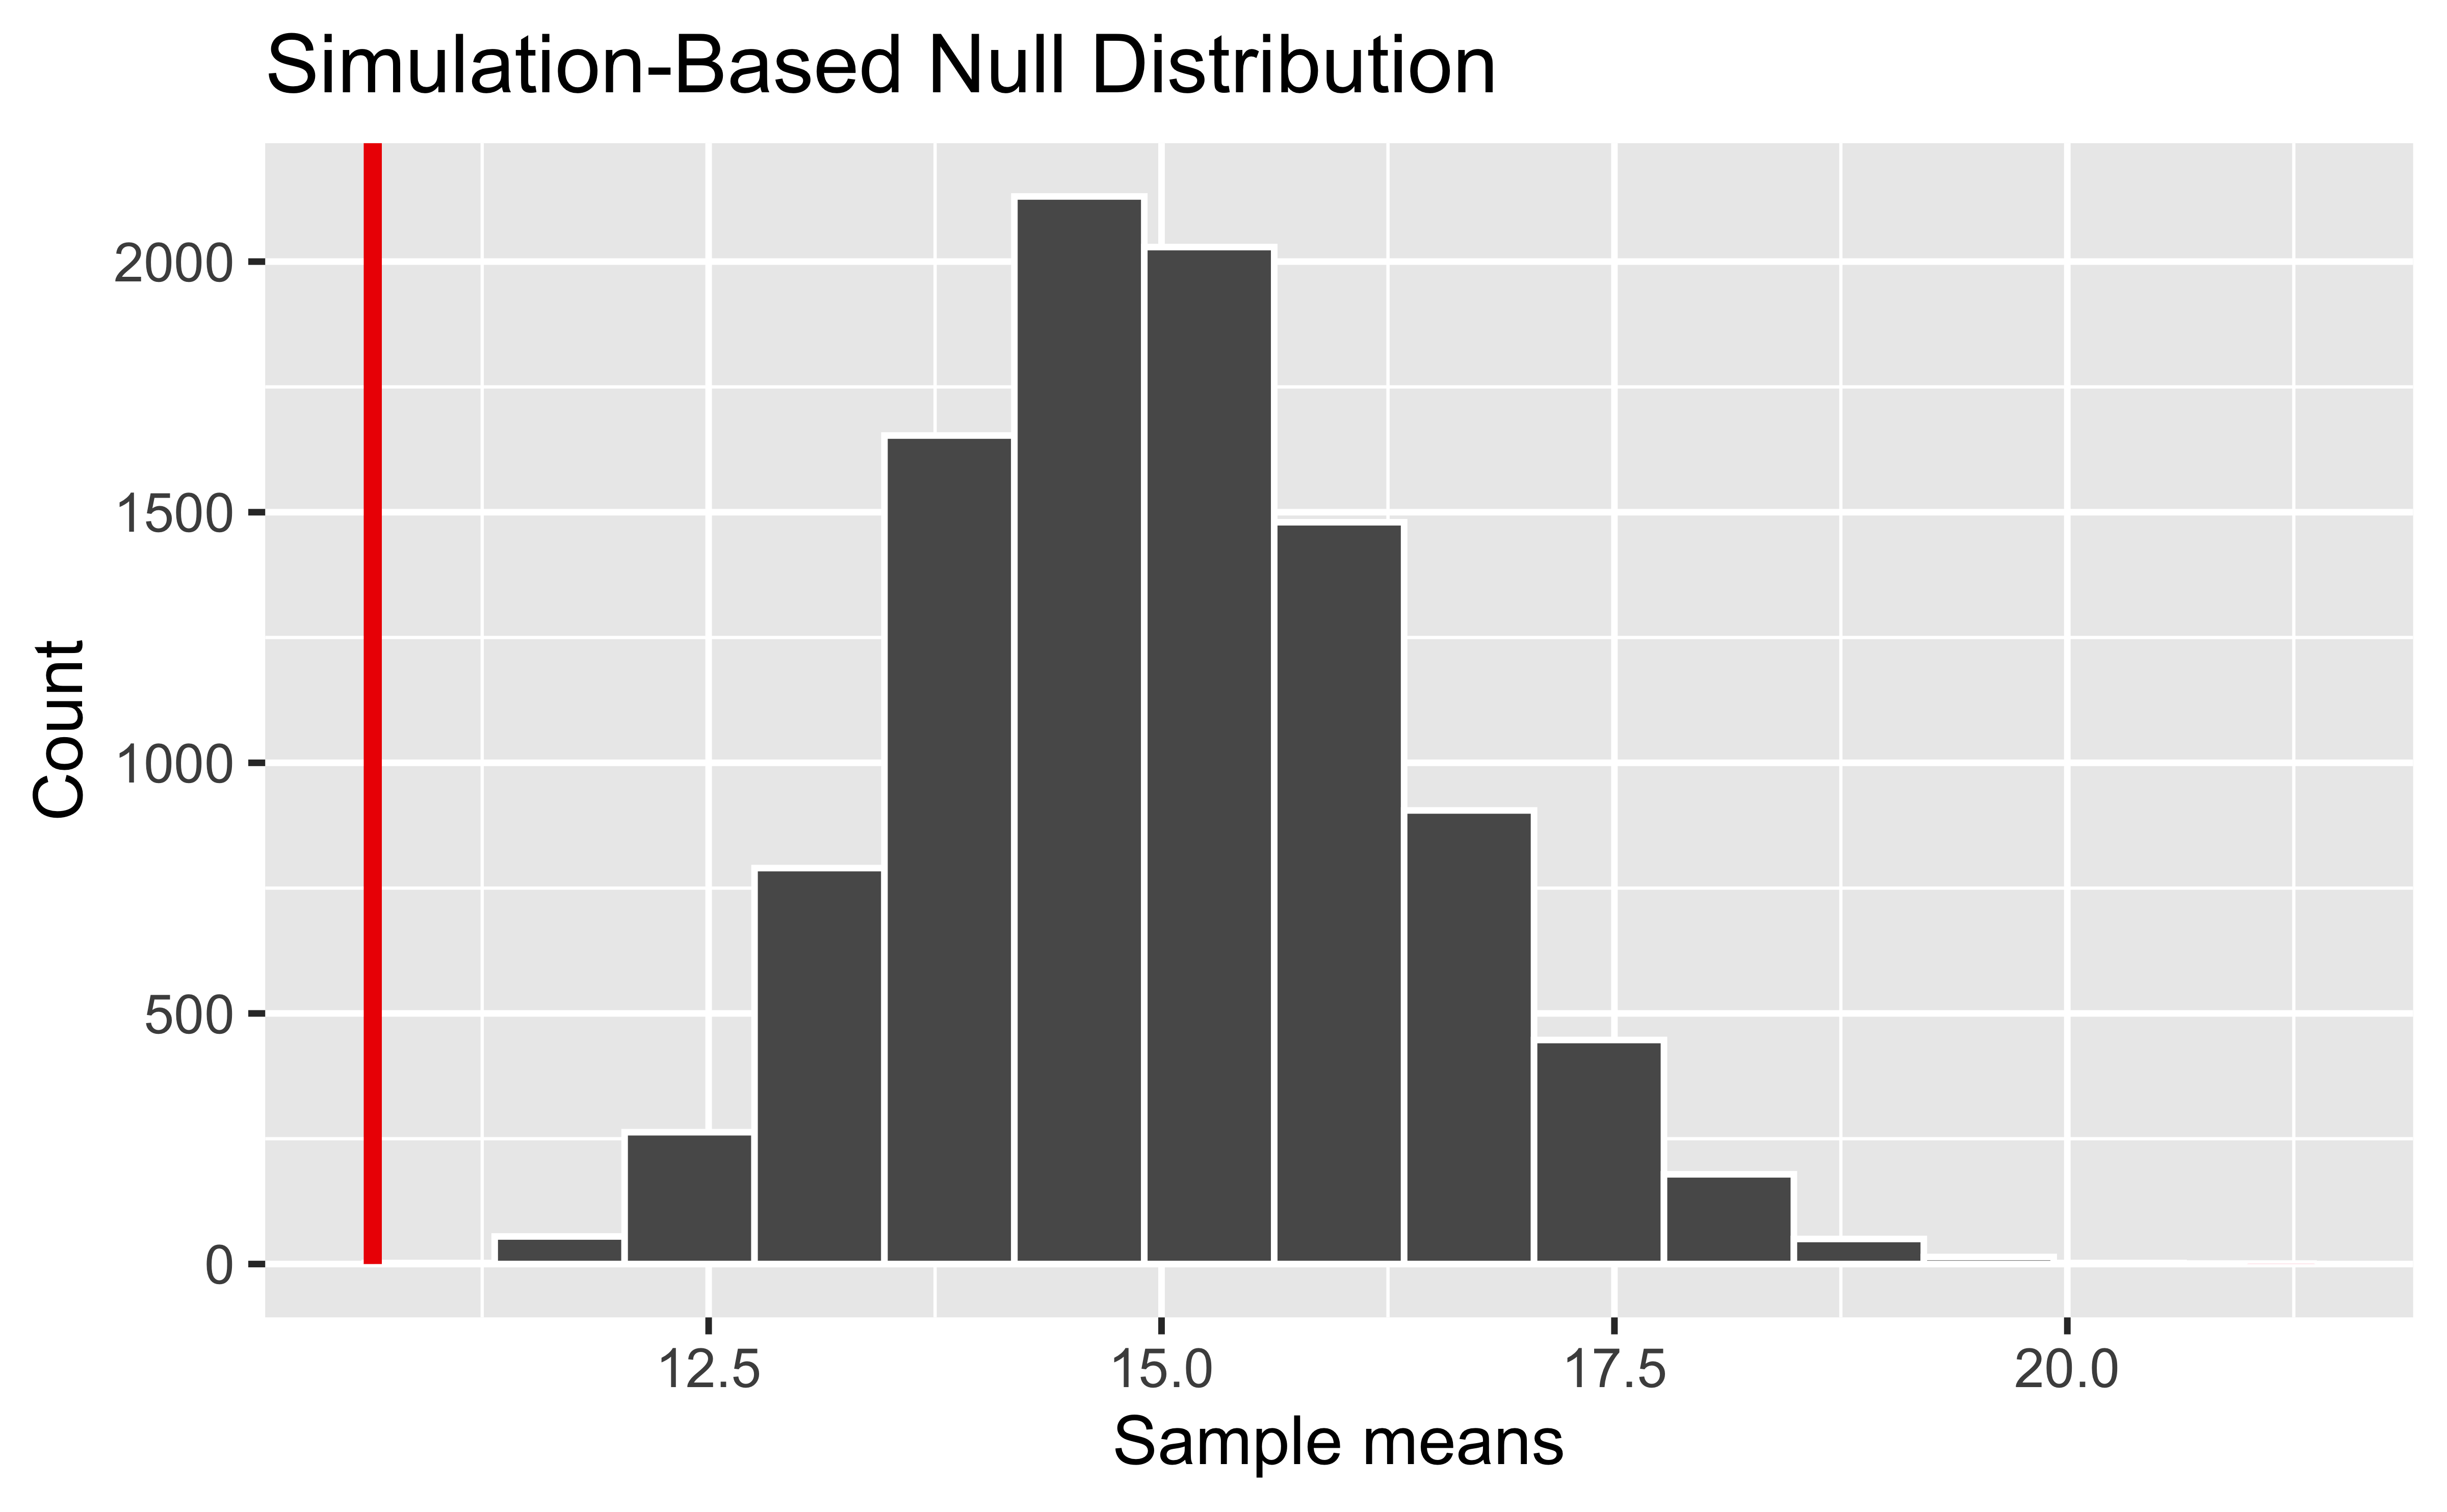
Let’s add our sample mean to this distribution and shade the p-value.
Notice our sample mean of 10.65 is below the mass of this distribution.
Now suppose instead we wanted to test \(H_0: \mu=10\). In this case, we would get a different result.
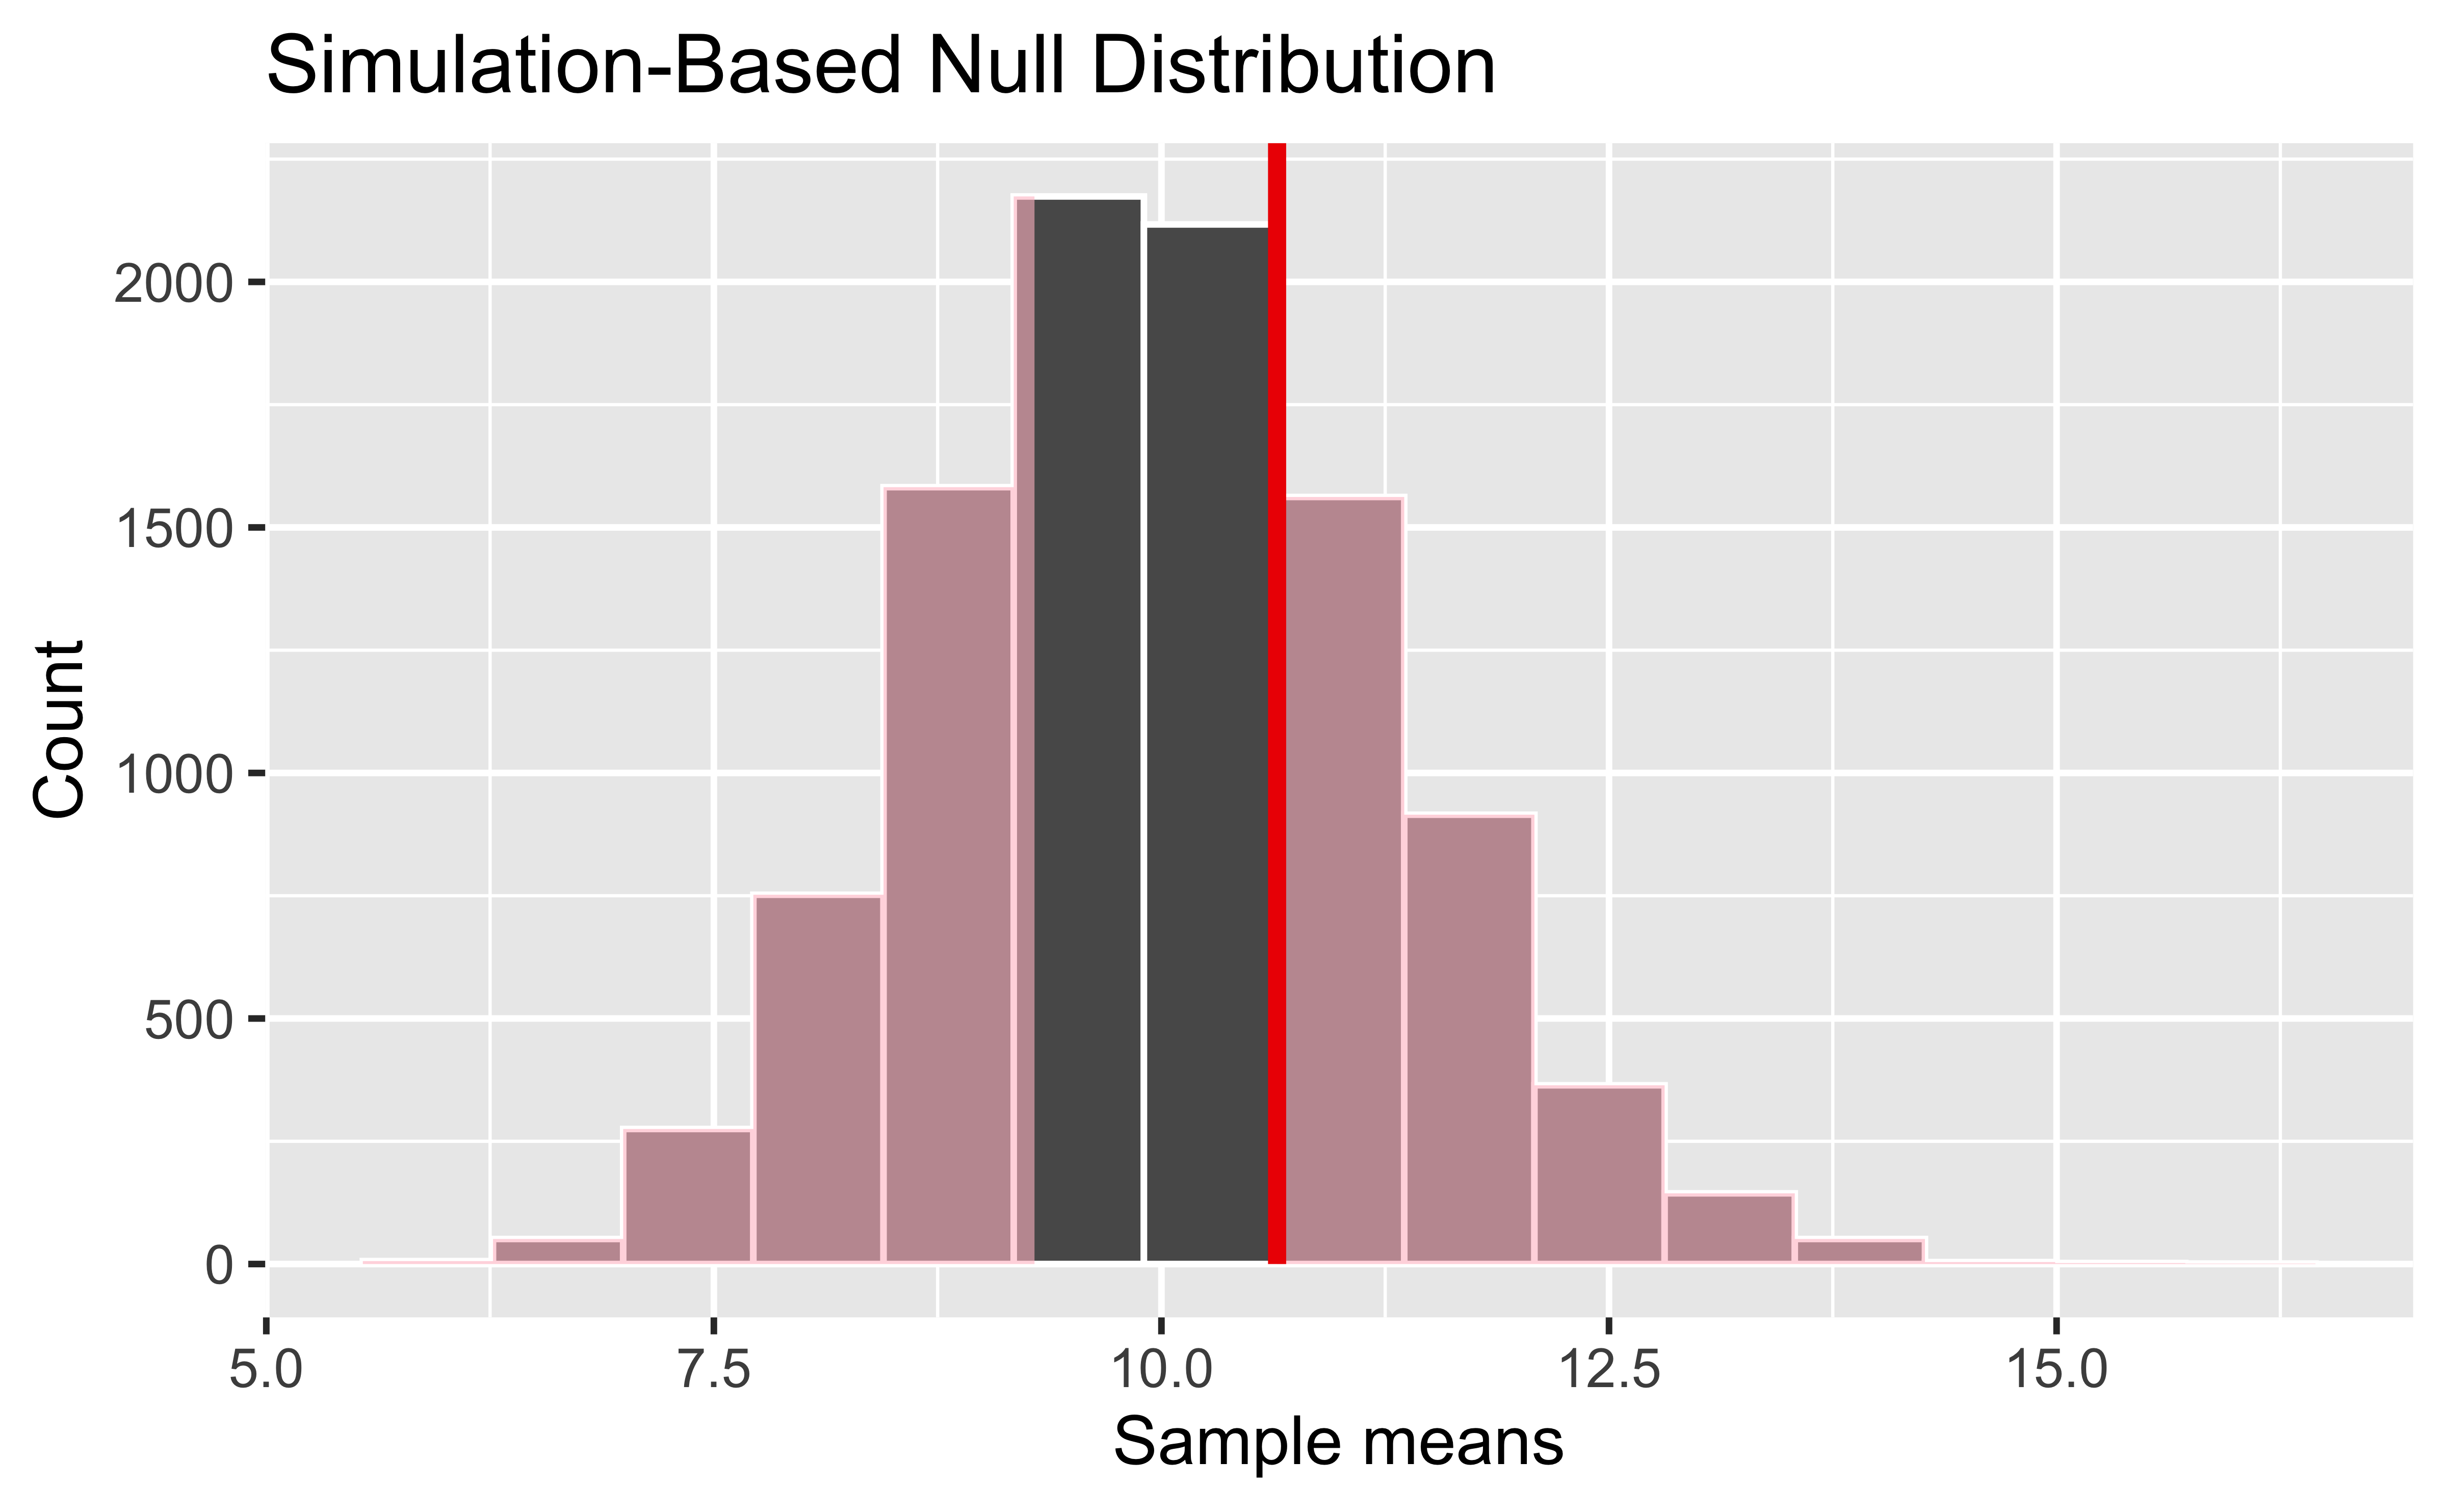
Now the p-value, corresponding to the pink shaded area, is quite large.
Suppose we wish to test the null hypothesis that 20% of Flint households have water with lead levels over 15 ppb, versus the alternative that this percentage is not 20%.
While we could use the Central Limit Theorem here, we actually have an even better option in R – we can carry out this test based on the (exact) binomial distribution. With the binomial distribution, we don’t have to worry about the sample size or rules of thumb for our test to be accurate. The Central Limit Theorem-based methods became very popular when computers were less powerful, but now we can use exact tests much more easily, even when large combinatorial calculations are involved.
This exact binomial test works in the same manner as the test we used earlier for fairness in hiring – but we can avoid doing it by hand using binom.test (you can go back and check that result!).
#>
#> Exact binomial test
#>
#> data: flintprop$countover15 and flintprop$n.lead
#> number of successes = 45, number of trials = 271, p-value
#> = 0.172
#> alternative hypothesis: true probability of success is not equal to 0.2
#> 95 percent confidence interval:
#> 0.1237721 0.2158079
#> sample estimates:
#> probability of success
#> 0.1660517
We can also explore this using simulation. For binary data, we can draw random samples from a Bernoulli distribution with probability of success equal to the value of p given in the code.
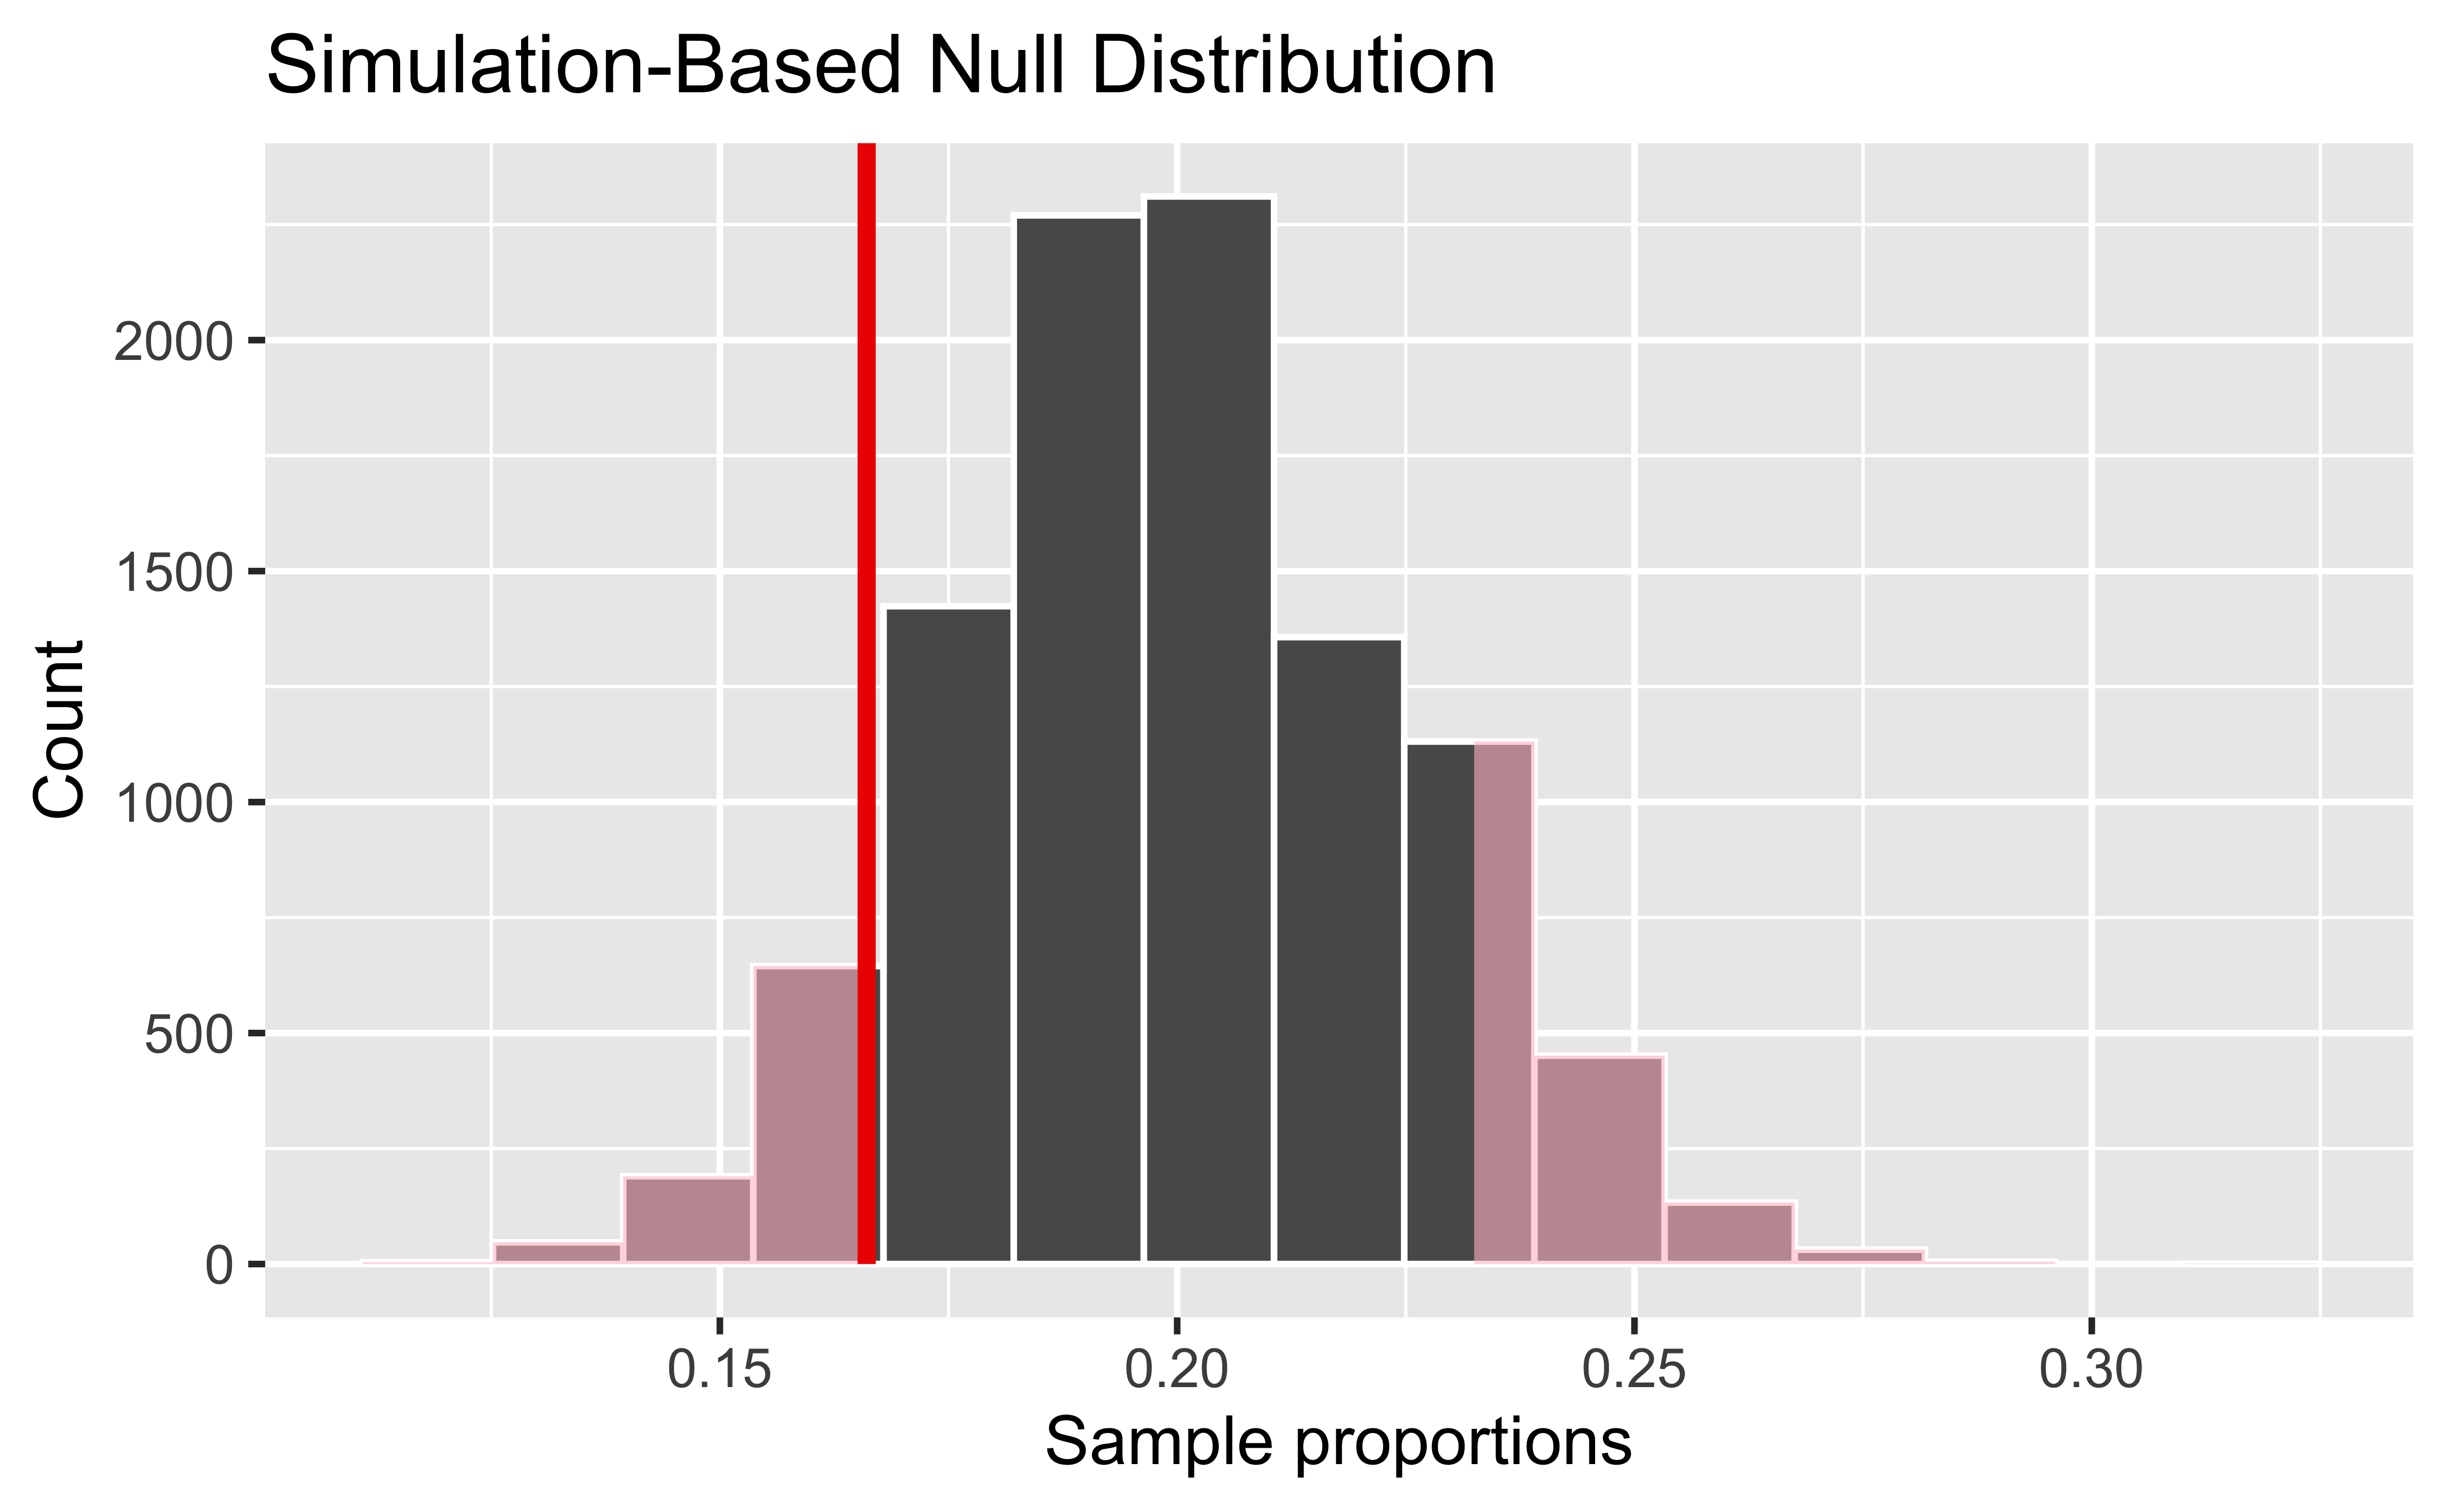
null_dist_20 <- flint %>%
mutate(Pbover15 = Pb_initial > 15) %>%
specify(response = Pbover15, success = "TRUE") %>%
hypothesize(null = "point", p = 0.2) %>%
generate(reps = 10000, type = "draw") %>%
calculate(stat = "prop")
visualize(null_dist_20) +
shade_p_value(obs_stat = flintprop$phat,
direction = "two-sided") +
labs(x = "Sample proportions", y = "Count")Public health officials often recommend that residents who have lead in their drinking water run the water for 45 seconds to 2 minutes (called “flushing”) to remove as much lead from the drinking water as possible. Does this really help?
In our data, we have two measures taken after flushing the pipes – one after 45 seconds, and one after two minutes.
The paired t-test is useful in situations like this one, where we have an initial measure as well as follow-up measures. We can simply subtract two measures to obtain a “difference” measure and then carry out a regular one-sample t-test.
Samples are often paired for a variety of reasons
Measurements are taken on a single subject at two distinct points in time (e.g., baseline and follow-up)
Subjects may be matched so that members of each pair are as much alike as possible with respect to important characteristics like age and gender (e.g., matched case-control study)
Pairing can control for unwanted sources of variation that might otherwise influence the results of a comparison. Matching within subject (e.g., baseline and follow-up) is a powerful way to eliminate subject-specific factors.
What if you use an unpaired test for paired data?
You will get the same estimates of the means
If the pairs have positive correlation (almost always the case if you paired correctly), the unpaired estimate of the variance will be larger than the paired estimate. This means the paired test has greater power.
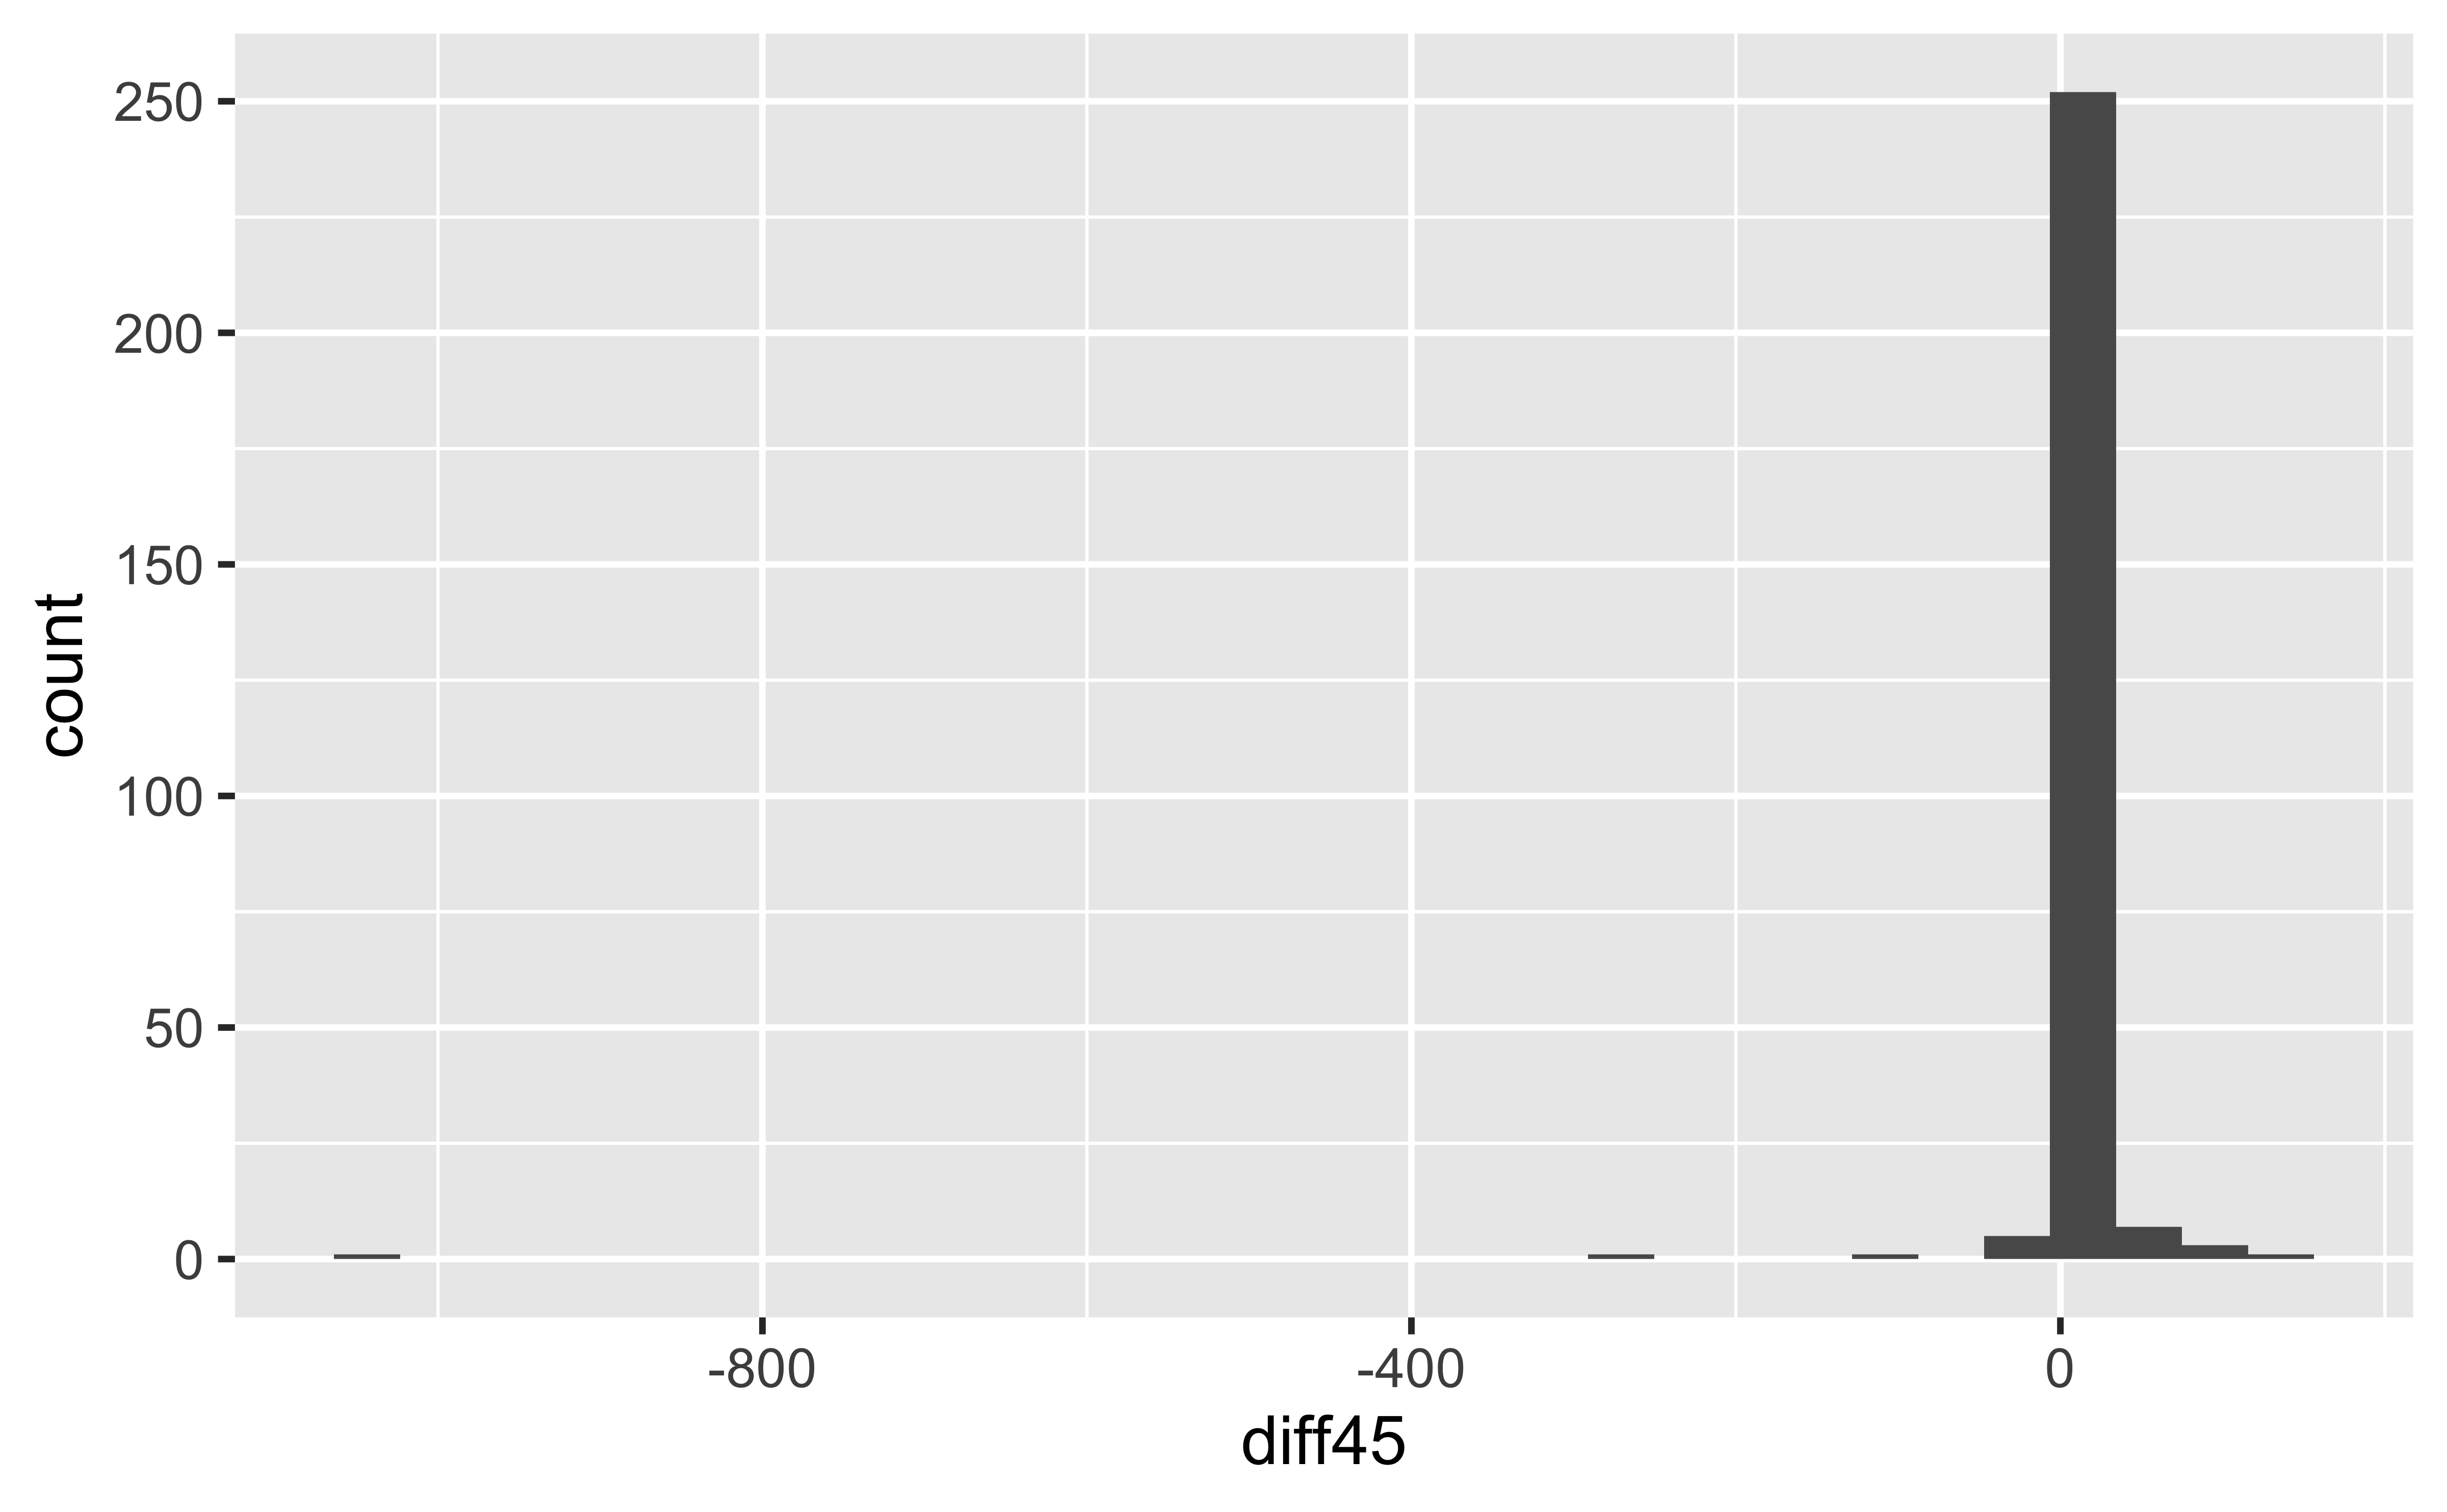
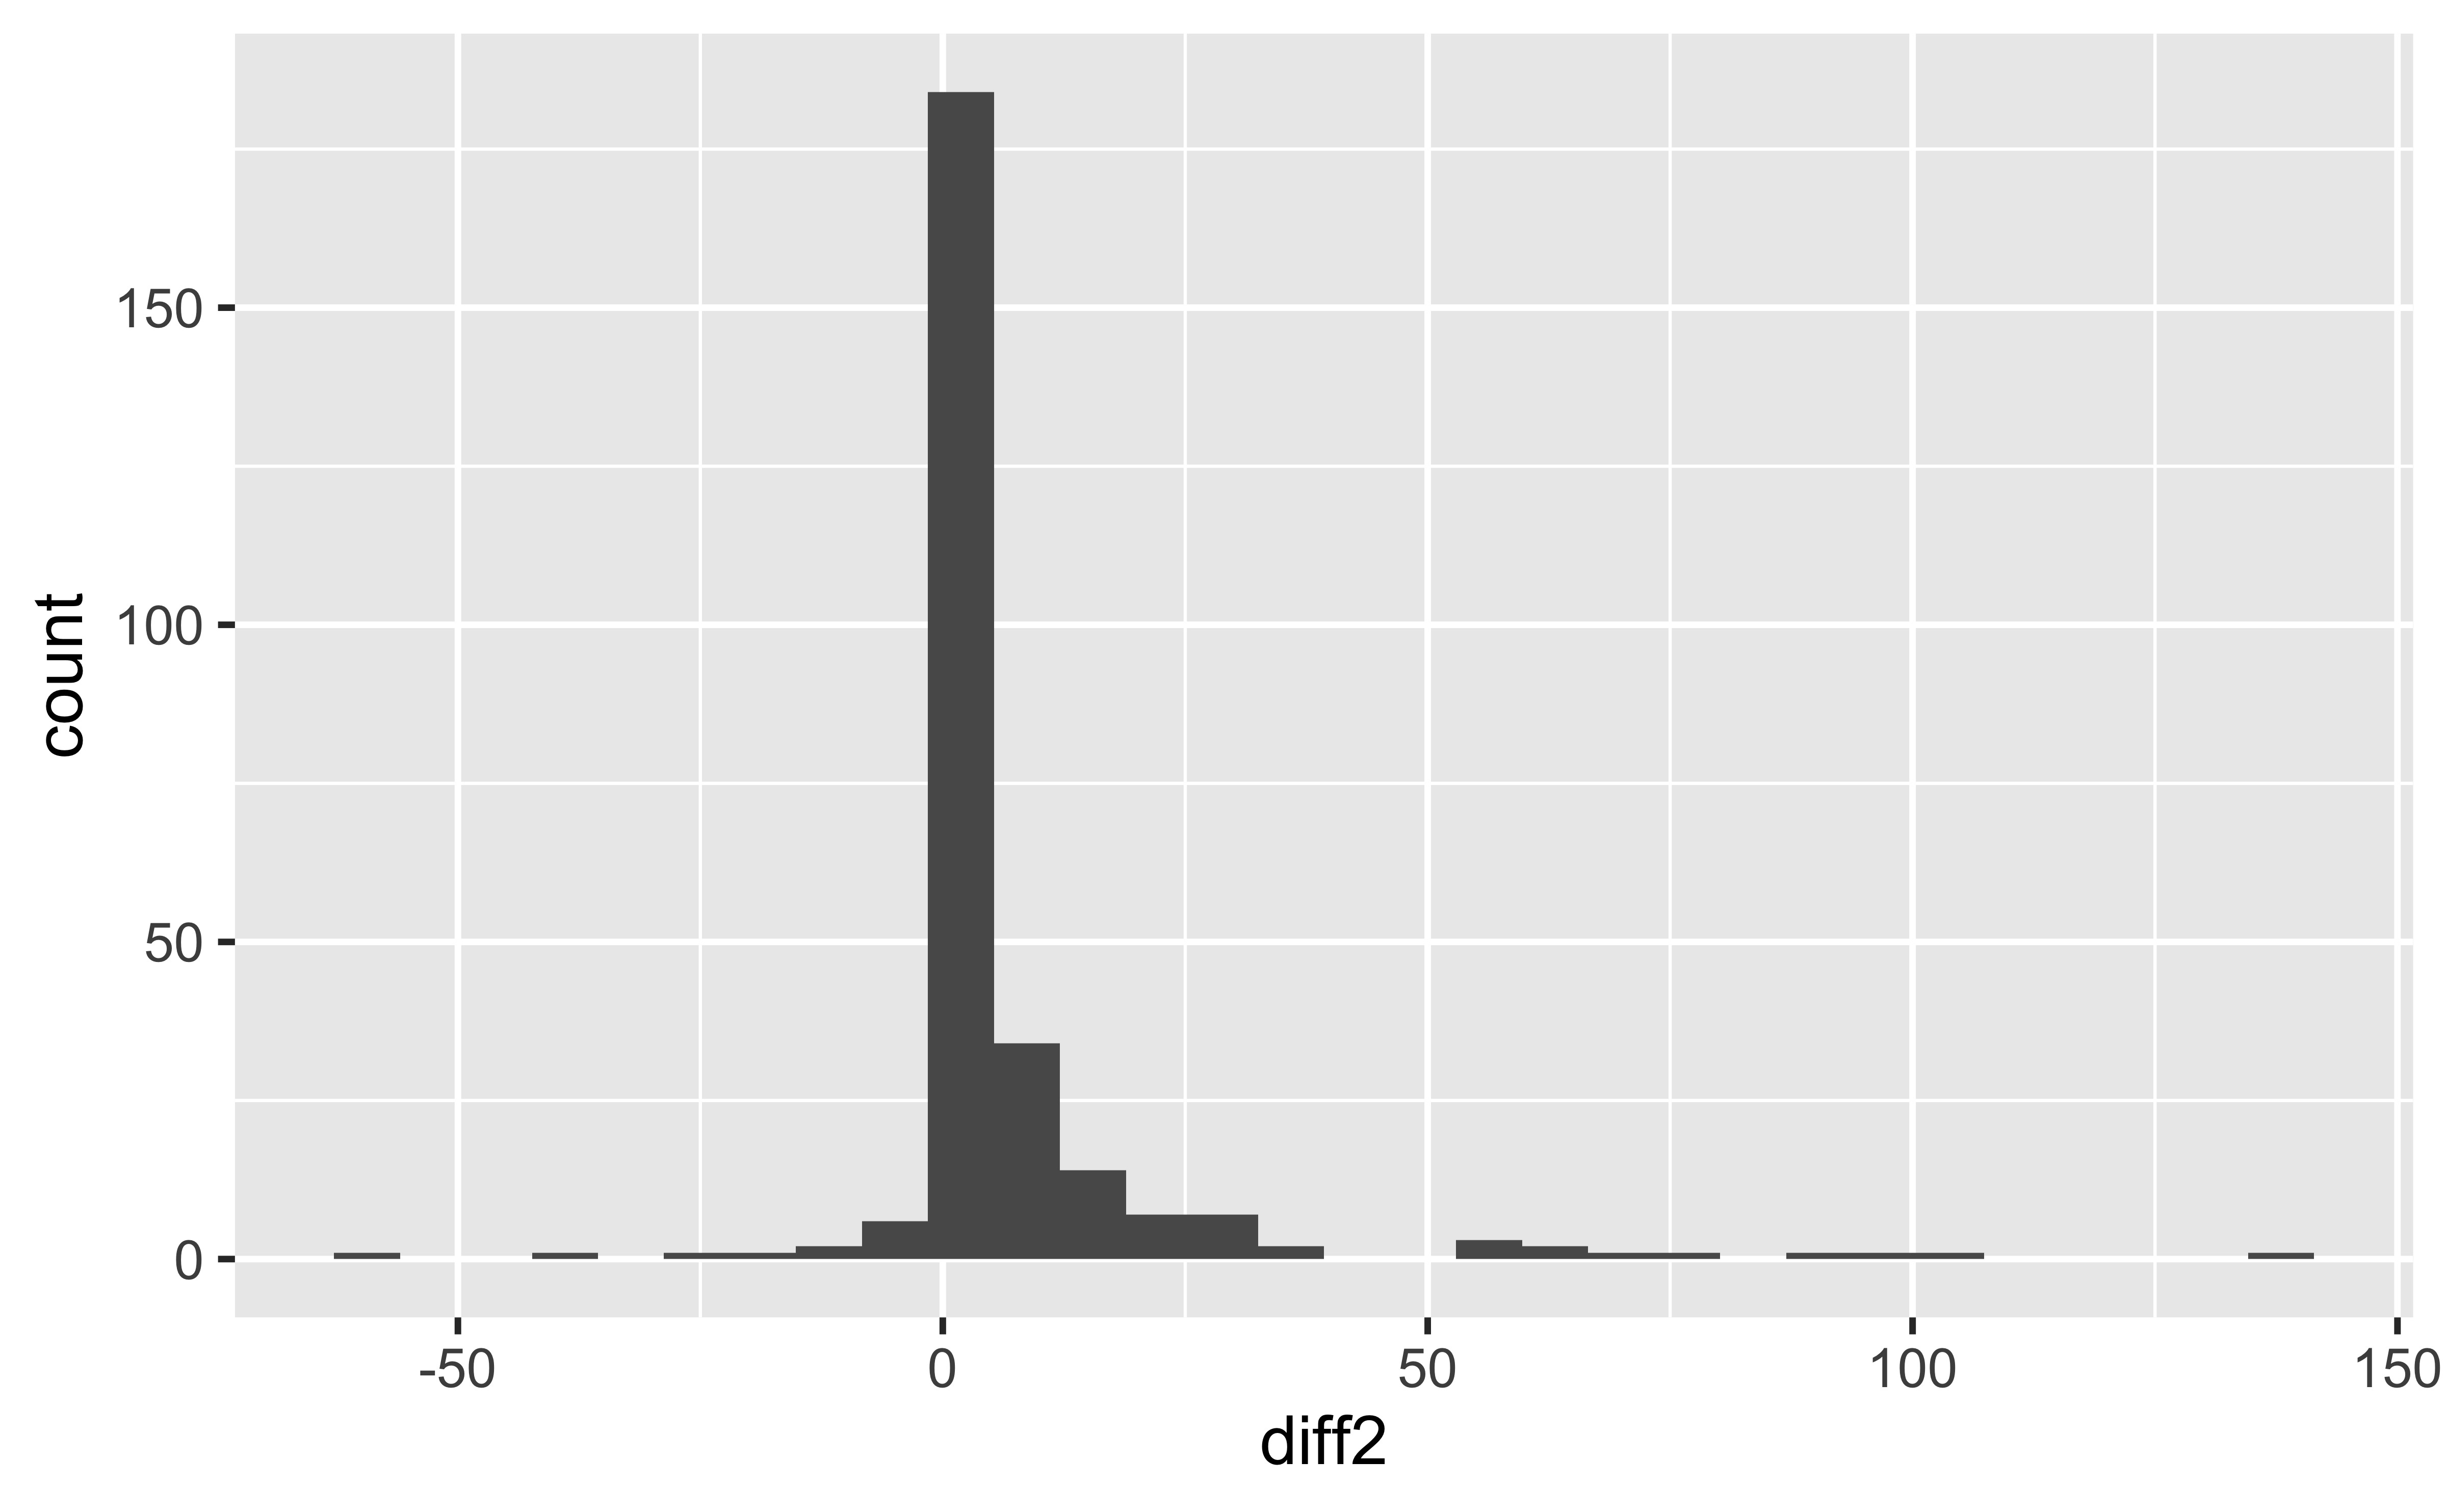
Create two new variables, calculated as (1) initial lead concentration minus the lead concentration after 45 seconds of flushing, and (2) initial lead concentration minus the lead concentration after 2 minutes of flushing. Then conduct two hypothesis tests: in each case, your goal is to evaluate whether the paired differences are 0. Interpret your results in terms of lead levels before and after flushing. Include useful graphical displays to supplement your test and interpretation.
#>
#> One Sample t-test
#>
#> data: flint$diff45
#> t = 0.083533, df = 270, p-value = 0.9335
#> alternative hypothesis: true mean is not equal to 0
#> 95 percent confidence interval:
#> -7.782909 8.472607
#> sample estimates:
#> mean of x
#> 0.3448487
#>
#> One Sample t-test
#>
#> data: flint$diff2
#> t = 6.3748, df = 270, p-value = 7.891e-10
#> alternative hypothesis: true mean is not equal to 0
#> 95 percent confidence interval:
#> 4.827963 9.142612
#> sample estimates:
#> mean of x
#> 6.985288
How do you interpret the results? Write a short paragraph explaining your findings.
In practice, we don’t usually test that a sample mean equals a single fixed value; instead, we want to compare responses across groups or across different values of covariates. The type of t-test we use to compare two means depends on how the samples were obtained.
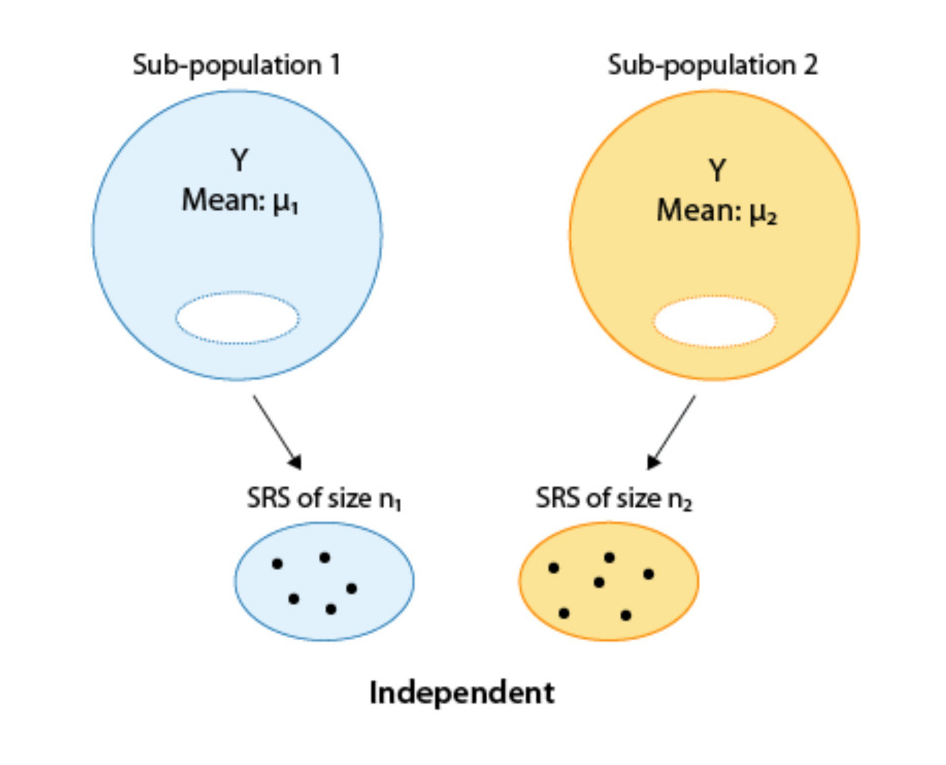
One approach would be to obtain two independent samples and test the equality of means \(\mu_1\) and \(\mu_2\).
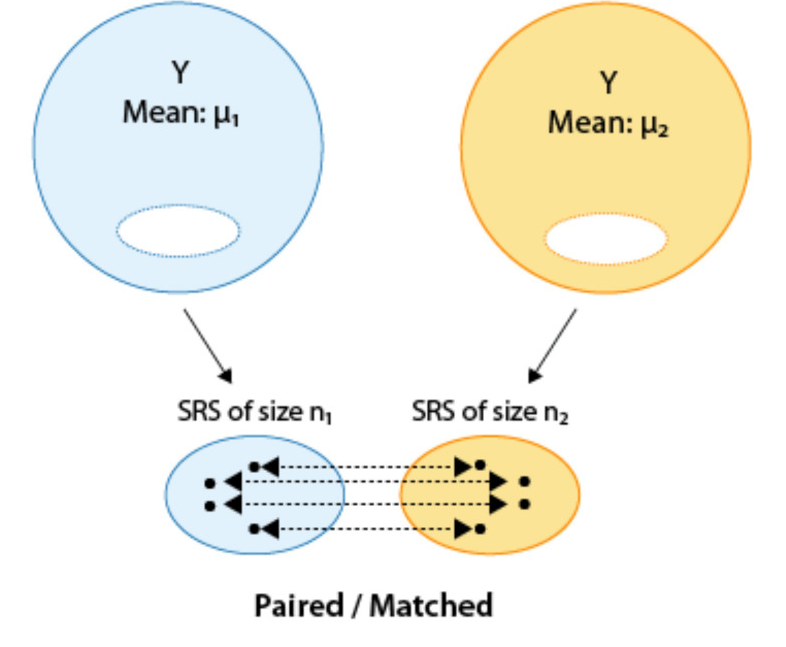
An alternative would be to obtain paired or matched samples and test the equality of means \(\mu_1\) and \(\mu_2\). Matching could be by person (e.g., before and after measures) or could be a pair of individuals who belong together in another way (e.g., same date of birth in same hospital, married partners).
Laws regarding the legal limit of blood alcohol while driving vary widely worldwide (some countries do not legislate this, while others have limits as low as 0%). Some studies have shown distraction to affect driving in similar ways as drinking.
Suppose a Department of Motor Vehicles wishes to compare impairment of drivers while texting to impairment after drinking two beers. Describe an independent samples design and a matched pairs design for this question of interest.
A random sample of college students who identified as either male or female answered the question “What is more important to you – personality or looks?” on a 25 point scale, where 1 indicates personality has maximum importance and looks don’t matter, and 25 indicates that looks have maximum importance and personality plays no role. The researcher was interested in whether gender plays a role in the importance of looks versus personality.
The null hypothesis is that males and females place the same emphasis on personality (score is unrelated to gender), while the alternative is that they do not (score is related to gender).
\[H_0: \mu_{MALE}=\mu_{FEMALE}\] \[H_A: \mu_{MALE}\neq\mu_{FEMALE}\]
OR equivalently,
\[H_0: \mu_{MALE}-\mu_{FEMALE}=0\] \[H_A: \mu_{MALE}-\mu_{FEMALE}\neq 0\]
The researcher enrolled 239 subjects and obtained complete data on 205, with 85 males and 120 females in the complete data sample.
Analyzing the data, we obtain \(\bar{x}_{MALE}=13.33\), \(\bar{x}_{FEMALE}=10.73\), \(s_{MALE}=4.02\), \(s_{FEMALE}=4.25\).
Recall: 1=only personality, 25=only looks
The two-sample t-test for independent samples is given by \[t=\frac{(\bar{x}_1-\bar{x}_2)-(\mu_1-\mu_2)}{\sqrt{s_1^2/{n_1}+s_2^2/n_2}}.\] The degrees of freedom (df) depend on whether or not \(\sigma_1=\sigma_2\).
The choice of df depends on whether the independent samples have the same, or different, variances. There are tests for this in R (e.g., bartlett.test()), but these tests have low power when sample sizes are not large and thus tends to tell you variances are equal in this setting when in fact, they may not be.
If the variances are equal, then we can use a pooled estimate of \(s^2\), and the degrees of freedom are given by \((n_1-1)+(n_2-1)=n_1+n_2-2\).
If the variances are unequal, the degrees of freedom are difficult to derive, and the Welch/Satterthwaite approximation is often used (software will do this for you), which is \(df=\frac{\left(\frac{s_1^2}{n_1}+\frac{s_2^2}{n_2}\right)^2}{\frac{1}{n_1-1}\left(\frac{s_1^2}{n_1}\right)^2+\frac{1}{n_2-1}\left(\frac{s_2^2}{n_2}\right)^2}\).
Unequal variances should be the default choice, as the t-test assuming equal variances can be quite unreliable if the variances differ, especially when the group sizes differ as well.
#>
#> Welch Modified Two-Sample t-Test
#>
#> data: Summarized x and y
#> t = 4.4548, df = 186.94, p-value = 1.444e-05
#> alternative hypothesis: true difference in means is not equal to 0
#> 95 percent confidence interval:
#> 1.44862 3.75138
#> sample estimates:
#> mean of x mean of y
#> 13.33 10.73
Based on both the test and the 95% confidence interval, we have evidence to reject the null hypothesis that males and females place the same emphasis on looks and personality. In this population, it appears that females place more emphasis on personality than males.
34 observations (14% of those enrolled) have missing responses
Because 120 women and 85 men responded, it may be the case that more men than women failed to respond (if all 34 missing observations were from men, would have balanced sample of 120 women and 119 men)
Perhaps many men failed to respond because they valued personality more than looks (but maybe did not want to admit it)
In this case it would be possible for these men’s responses to overturn the result (having a mean score for men lower than that for women is mathematically possible for this percentage of missing data)
Be cautious about results of hypothesis testing in the presence of missing data.
At high altitude, lower atmospheric oxygen creates a physiological challenge: the body must still deliver enough oxygen to its tissues. One way humans can respond is by increasing the concentration of hemoglobin, the oxygen-carrying protein in red blood cells.
Researchers studying high-altitude adaptation in Ethiopia measured hemoglobin concentrations among members of two populations living at high altitude: the Amhara, living at approximately 3,700 meters, and the Oromo, living at approximately 4,000 meters.
Among iron-replete men (men with adequate iron levels), researchers observed the following:
| Population | Altitude | Sample size | Mean hemoglobin | SD |
|---|---|---|---|---|
| Amhara | 3,700 m | 99 | 16.7 g/dL | 1.1 g/dL |
| Oromo | 4,000 m | 66 | 18.7 g/dL | 1.7 g/dL |
We want to investigate whether mean hemoglobin concentration differs between these two high-altitude populations.
1. Define the parameters. Let \(\mu_A\) represent the mean hemoglobin concentration among Amhara men living at high altitude and \(\mu_O\) represent the mean among Oromo men living at high altitude.
Write the null and alternative hypotheses for the research question.
2. Choose an analysis. What statistical test would you use to compare mean hemoglobin concentration between these two groups? Briefly explain why this test is appropriate.
3. Conduct the test in R. Use the summary statistics to perform a two-sample t-test. Assume that the population variances are not necessarily equal.
Report the following:
4. Interpret the results. Based on your hypothesis test, is there evidence that mean hemoglobin concentration differs between Amhara and Oromo men living at high altitude? Explain your conclusion in plain language.
5. Statistical significance vs. scientific importance. Does a small p-value tell us whether the observed difference in sample means is physiologically important? Explain.
What happens to the human body when we move to high altitude? Design a study to investigate how a physiological measure, such as blood oxygen saturation or hemoglobin concentration, changes when people move from low to high altitude. Describe who you would study, what you would measure, and when you would take the measurements. Then propose an appropriate statistical analysis for determining whether the physiological measure changes, on average, with altitude.